Exam Dumps Databricks-Machine-Learning-Professional Practice Free Latest Databricks Practice Tests
Databricks-Machine-Learning-Professional Exam Questions | Real Databricks-Machine-Learning-Professional Practice Dumps
Databricks Databricks-Machine-Learning-Professional Exam Syllabus Topics:
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
| Topic 5 |
|
| Topic 6 |
|
| Topic 7 |
|
NEW QUESTION # 30
A machine learning engineer and data scientist are working together to convert a batch deployment to an always-on streaming deployment. The machine learning engineer has expressed that rigorous data tests must be put in place as a part of their conversion to account for potential changes in data formats.
Which of the following describes why these types of data type tests and checks are particularly important for streaming deployments?
- A. Because the streaming deployment is always on, all types of data must be handled without producing an error
- B. None of these statements
- C. Because the streaming deployment is always on, there is a need to confirm that the deployment can autoscale
- D. All of these statements
- E. Because the streaming deployment is always on, there is no practitioner to debug poor model performance
Answer: C
NEW QUESTION # 31
Which of the following MLflow operations can be used to delete a model from the MLflow Model Registry?
- A. client.update_registered_model
- B. client.delete_model_version
- C. client.transition_model_version_stage
- D. client.delete_registered_model
- E. client.delete_model
Answer: D
NEW QUESTION # 32
Which of the following MLflow operations can be used to automatically calculate and log a Shapley feature importance plot?
- A. None of these operations can accomplish the task.
- B. client.log_artifact
- C. mlflow.log_figure
- D. mlflow.shap.log_explanation
- E. mlflow.shap
Answer: E
NEW QUESTION # 33
Which of the following is a simple statistic to monitor for categorical feature drift?
- A. Mode
- B. Percentage of missing values
- C. None of these
- D. Number of unique values
- E. Mode, number of unique values, and percentage of missing values
Answer: E
NEW QUESTION # 34
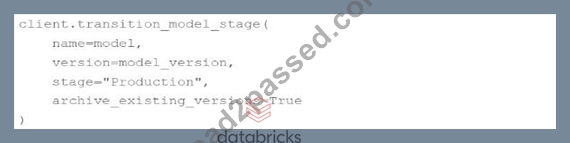
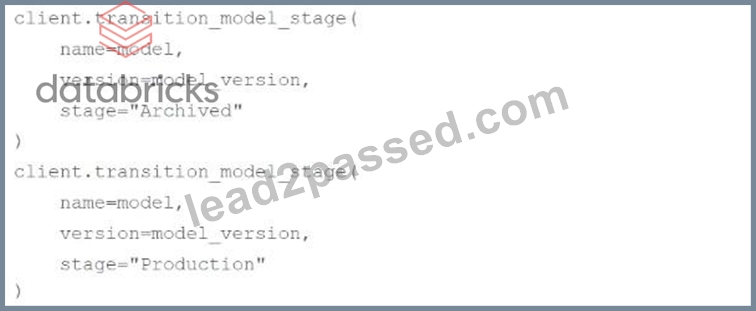
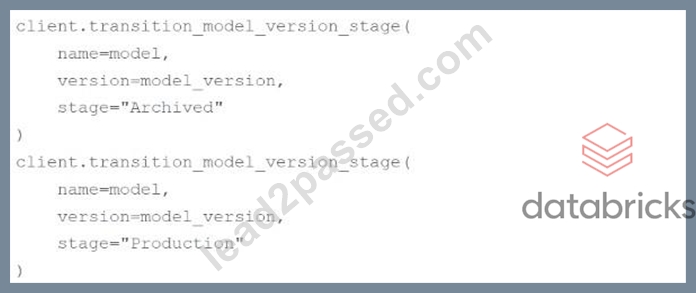
A machine learning engineer wants to move their model version model_version for the MLflow Model Registry model model from the Staging stage to the Production stage using MLflow Client client. At the same time, they would like to archive any model versions that are already in the Production stage.
Which of the following code blocks can they use to accomplish the task?
- A.
- B.
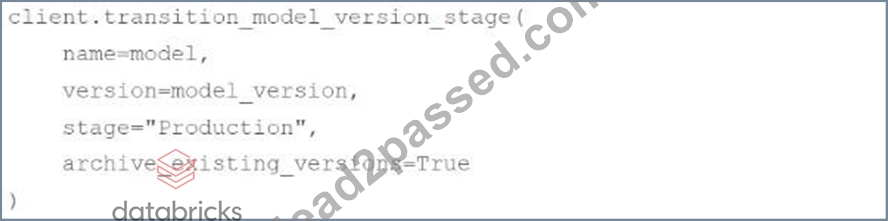
- C.
- D.
Answer: A
NEW QUESTION # 35
A data scientist has written a function to track the runs of their random forest model. The data scientist is changing the number of trees in the forest across each run.
Which of the following MLflow operations is designed to log single values like the number of trees in a random forest?
- A. There is no way to store values like this.
- B. mlflow.log_param
- C. mlflow.log_model
- D. mlflow.log_metric
- E. mlflow.log_artifact
Answer: D
NEW QUESTION # 36
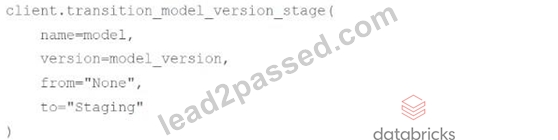
A machine learning engineer has created a webhook with the following code block: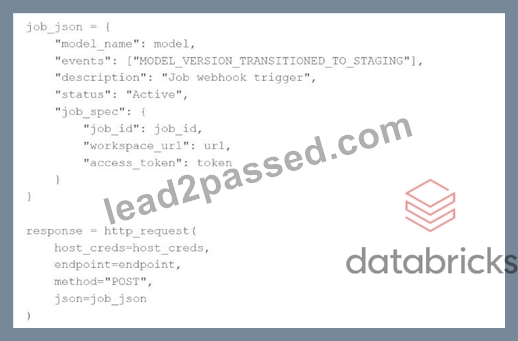
Which of the following code blocks will trigger this webhook to run the associate job?
- A.
- B.
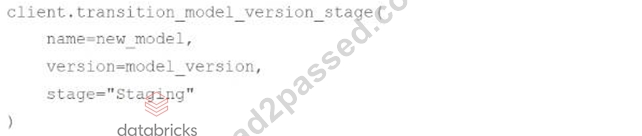
- C.
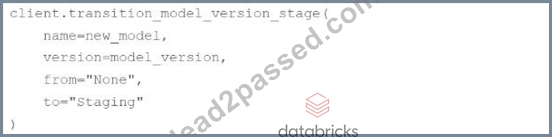
- D.
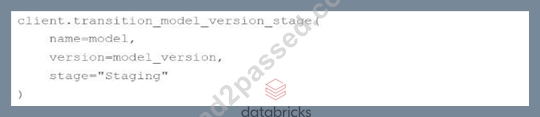
- E.
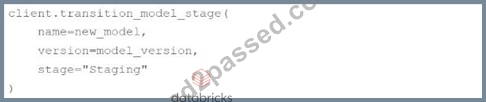
Answer: A
NEW QUESTION # 37
A data scientist has developed a scikit-learn random forest model model, but they have not yet logged model with MLflow. They want to obtain the input schema and the output schema of the model so they can document what type of data is expected as input.
Which of the following MLflow operations can be used to perform this task?
- A. mlflow.models.schema.infer_schema
- B. mlflow.models.Model.get_input_schema
- C. mlflow.models.Model.signature
- D. mlflow.models.signature.infer_signature
- E. There is no way to obtain the input schema and the output schema of an unlogged model.
Answer: A
NEW QUESTION # 38
A machine learning engineer wants to log feature importance data from a CSV file at path importance_path with an MLflow run for model model.
Which of the following code blocks will accomplish this task inside of an existing MLflow run block?
A)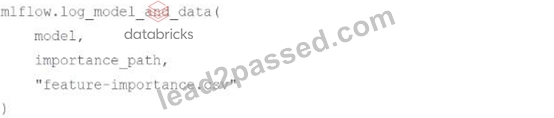
B)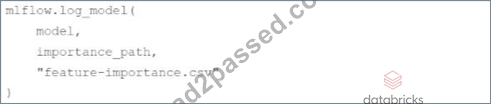
C) mlflow.log_data(importance_path, "feature-importance.csv")
D) mlflow.log_artifact(importance_path, "feature-importance.csv")
E) None of these code blocks tan accomplish the task.
- A. Option B
- B. Option D
- C. Option C
- D. Option E
- E. Option A
Answer: E
NEW QUESTION # 39
Which of the following tools can assist in real-time deployments by packaging software with its own application, tools, and libraries?
- A. None of these tools
- B. REST APIs
- C. Cloud-based compute
- D. Autoscaling clusters
- E. Containers
Answer: C
NEW QUESTION # 40
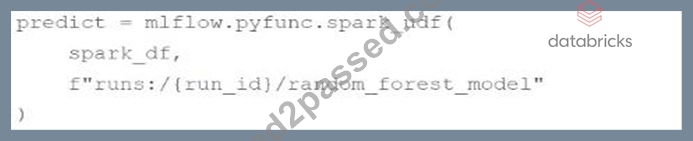
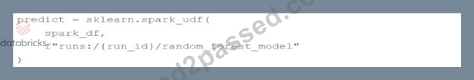
A machine learning engineer has developed a random forest model using scikit-learn, logged the model using MLflow as random_forest_model, and stored its run ID in the run_id Python variable. They now want to deploy that model by performing batch inference on a Spark DataFrame spark_df.
Which of the following code blocks can they use to create a function called predict that they can use to complete the task?
- A.
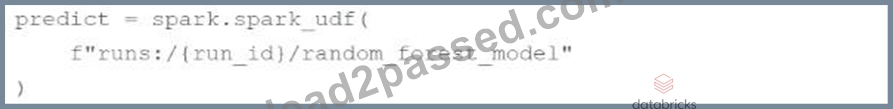
- B.
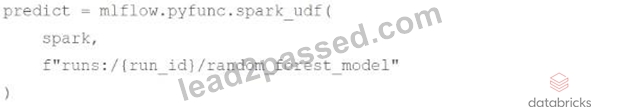
- C. It is not possible to deploy a scikit-learn model on a Spark DataFrame.
- D.
- E.
Answer: A
NEW QUESTION # 41
Which of the following is an advantage of using the python_function(pyfunc) model flavor over the built-in library-specific model flavors?
- A. python_function provides no benefits over the built-in library-specific model flavors
- B. python_function can be used to store models in an MLmodel file
- C. python_function can be used to deploy models without worrying about which library was used to create the model
- D. python_function can be used to deploy models in a parallelizable fashion
- E. python_function can be used to deploy models without worrying about whether they are deployed in batch, streaming, or real-time environments
Answer: D
NEW QUESTION # 42
Which of the following describes label drift?
- A. None of these describe label drift
- B. Label drift is when there is a change in the distribution of a target variable
- C. Label drift is when there is a change in the relationship between input variables and target variables
- D. Label drift is when there is a change in the distribution of the predicted target given by the model
- E. Label drift is when there is a change in the distribution of an input variable
Answer: E
NEW QUESTION # 43
Which of the following deployment paradigms can centrally compute predictions for a single record with exceedingly fast results?
- A. Streaming
- B. Real-time
- C. None of these strategies will accomplish the task.
- D. Edge/on-device
- E. Batch
Answer: A
NEW QUESTION # 44
A machine learning engineer is converting a Hyperopt-based hyperparameter tuning process from manual MLflow logging to MLflow Autologging. They are trying to determine how to manage nested Hyperopt runs with MLflow Autologging.
Which of the following approaches will create a single parent run for the process and a child run for each unique combination of hyperparameter values when using Hyperopt and MLflow Autologging?
- A. There is no way to accomplish nested runs with MLflow Autoloqqinq and Hyperopt
- B. Starting a manual child run within the objective function
- C. Ensuring that a built-in model flavor is used for the model logging
- D. MLflow Autoloqqinq will automatically accomplish this task with Hyperopt
- E. Startinq a manual parent run before calling fmin
Answer: E
NEW QUESTION # 45
Which of the following is a reason for using Jensen-Shannon (JS) distance over a Kolmogorov-Smirnov (KS) test for numeric feature drift detection?
- A. None of these reasons
- B. All of these reasons
- C. JS does not require any manual threshold or cutoff determinations
- D. JS is more robust when working with large datasets
- E. JS is not normalized or smoothed
Answer: D
NEW QUESTION # 46
A machine learning engineer wants to log and deploy a model as an MLflow pyfunc model. They have custom preprocessing that needs to be completed on feature variables prior to fitting the model or computing predictions using that model. They decide to wrap this preprocessing in a custom model class ModelWithPreprocess, where the preprocessing is performed when calling fit and when calling predict. They then log the fitted model of the ModelWithPreprocess class as a pyfunc model.
Which of the following is a benefit of this approach when loading the logged pyfunc model for downstream deployment?
- A. The same preprocessing logic will automatically be applied when calling predict
- B. There is no longer a need for pipeline-like machine learning objects
- C. The same preprocessing logic will automatically be applied when calling fit
- D. This approach has no impact when loading the logged Pvfunc model for downstream deployment
- E. The pvfunc model can be used to deploy models in a parallelizable fashion
Answer: B
NEW QUESTION # 47
A data scientist is utilizing MLflow to track their machine learning experiments. After completing a series of runs for the experiment with experiment ID exp_id, the data scientist wants to programmatically work with the experiment run data in a Spark DataFrame. They have an active MLflow Client client and an active Spark session spark.
Which of the following lines of code can be used to obtain run-level results for exp_id in a Spark DataFrame?
- A. spark.read.format("delta").load(exp_id)
- B. client.list_run_infos(exp_id)
- C. mlflow.search_runs(exp_id)
- D. There is no way to programmatically return row-level results from an MLflow Experiment.
- E. spark.read.format("mlflow-experiment").load(exp_id)
Answer: A
NEW QUESTION # 48
......
Verified Databricks-Machine-Learning-Professional Exam Dumps Q&As - Provide Databricks-Machine-Learning-Professional with Correct Answers: https://www.lead2passed.com/Databricks/Databricks-Machine-Learning-Professional-practice-exam-dumps.html
Pass Your Databricks-Machine-Learning-Professional Dumps Free Latest Databricks Practice Tests: https://drive.google.com/open?id=1_w82HMrdsLhsiVlkb0d3znhEWt3E9CRU